WellSaid
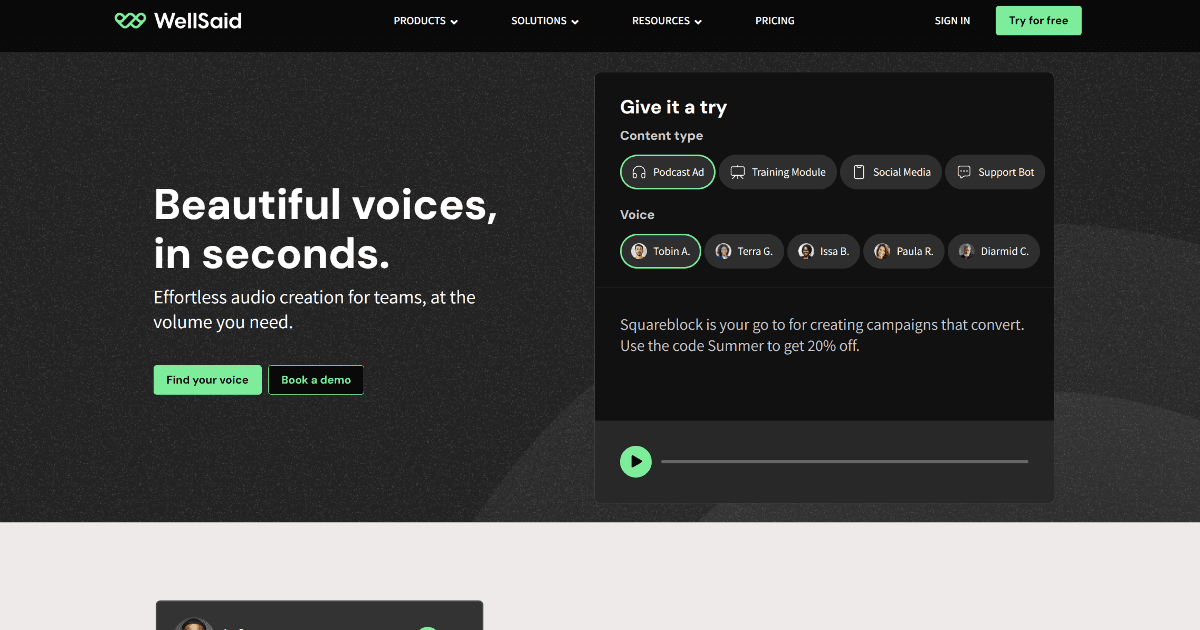
Transform text into lifelike, customizable spoken audio.
Monthly Visits
42.8K
Avg. Session Duration
N/A
Category Rank
N/A
Bounce Rate
23.5%
What is WellSaid?
WellSaid leads in transforming text-to-speech technology, offering remarkably lifelike and expressive voice synthesis. It simplifies creating high-quality spoken audio content for content creators, businesses, and educators across various applications like audiobooks, educational videos, and corporate training materials.
Key Features of WellSaid?
Pricing
- Trial Plan: Free. A 1-week trial with access to Studio and API features. Includes all functionality, but downloading is disabled.
- Creative Plan: $99 per month. Ideal for individuals. Includes 20 projects, 250 downloads per month, all English voices, unlimited retakes, 1 seat, and MP3 file output.
- Business Plan: $199 per user per month (billed yearly). For teams getting started. Includes everything in Creative, plus 100 projects per user, 9,000 downloads, team workspaces, Adobe and Canva integrations, live chat support, and more file format options.
- Enterprise Plan: Contact for pricing. Built for larger teams. Includes everything in Business, plus unlimited projects and downloads, SSO, priority support, content moderation, SOC2 security, and a dedicated Customer Success Manager.
Disclaimer: For current pricing details, refer to the official WellSaid website.
Alternatives to WellSaid

freetts
FreeTTS is an AI-powered online tool that converts text into high-quality, natural-sounding speech, supporting over 69 languages and accents. The platform combines text-to-speech functionality with audio editing features such as vocal removal, audio enhancement, cutting, and merging. Designed for ease of use, it caters to educators, content creators, marketers, and developers, offering customizable voice parameters, batch processing, and SSML support. FreeTTS provides both a free tier and premium paid plans, all accessible through a user-friendly web interface without the need for installation.

text-reader-ai
Text Reader AI is an advanced text-to-speech (TTS) solution that converts written content into natural, human-like audio within seconds. Powered by AI algorithms and high-quality WaveNet voices, it supports multiple languages and accents, making it ideal for applications in accessibility, education, content creation, and customer engagement. The platform enables voiceovers for podcasts, videos, audiobooks, and more, with the ability to download audio files in MP3 format for easy distribution. Featuring a clean and user-friendly interface, along with continuously improving AI, it ensures consistently realistic and natural-sounding speech output suitable for a wide range of uses.

audiobot
AudioBot is a cloud-based text-to-speech service that converts written text into lifelike audio in over 100 languages and accents. With more than 500 realistic voices, it leverages advanced deep learning to deliver natural-sounding speech. The platform supports multiple audio formats and features an intuitive interface, making it ideal for content creators, educators, marketers, and businesses seeking professional audio narration, voiceovers, or multilingual audio content.

inpodcast-ai
Inpodcast AI is an advanced podcast generation suite designed to streamline and accelerate the podcast production process by converting various text inputs—such as documents, PDFs, scripts, and plain text—into natural, fluent podcast audio. Supporting multiple document formats and offering over 70 voice styles and 30 languages, it enables creators to produce high-quality, customizable audio content without requiring technical expertise or recording equipment. The platform also includes script editing, intelligent pacing, and sound design tools, making it ideal for educators, content creators, and businesses looking to expand their reach through audio content.

typecast-ai
Typecast AI is an advanced AI voice generation platform that converts text into realistic speech with precise control over tone, pitch, speed, and emotion. Powered by its proprietary Speech Synthesis Foundation Model (SSFM), Typecast delivers natural and expressive speech in over 20 languages. The platform offers access to more than 550 AI voice actors and virtual avatars, enabling users to efficiently produce audio and video content without the need for traditional voice recording studios. With an intuitive interface and seamless integration capabilities, Typecast streamlines workflows for content creators, educators, marketers, and developers.

unreal-speech
Unreal Speech is a cutting-edge AI-powered text-to-speech platform that delivers high-quality, natural-sounding voice synthesis at a significantly lower cost than competing solutions. It supports ultra-low latency real-time audio streaming and offers a wide selection of languages and voices. Designed for developers, the platform features easy API integration and advanced customization options such as pitch, speaking rate, and emotion. It is ideal for content creators, educators, and enterprises seeking to enhance accessibility, interactivity, and automation.


