
urltotext
Web text extraction tool that converts URLs into clean text or Markdown format
Monthly Visits
84.3K
Avg. Session Duration
0 min
Category Rank
#3050
Bounce Rate
0.5%
What is urltotext?
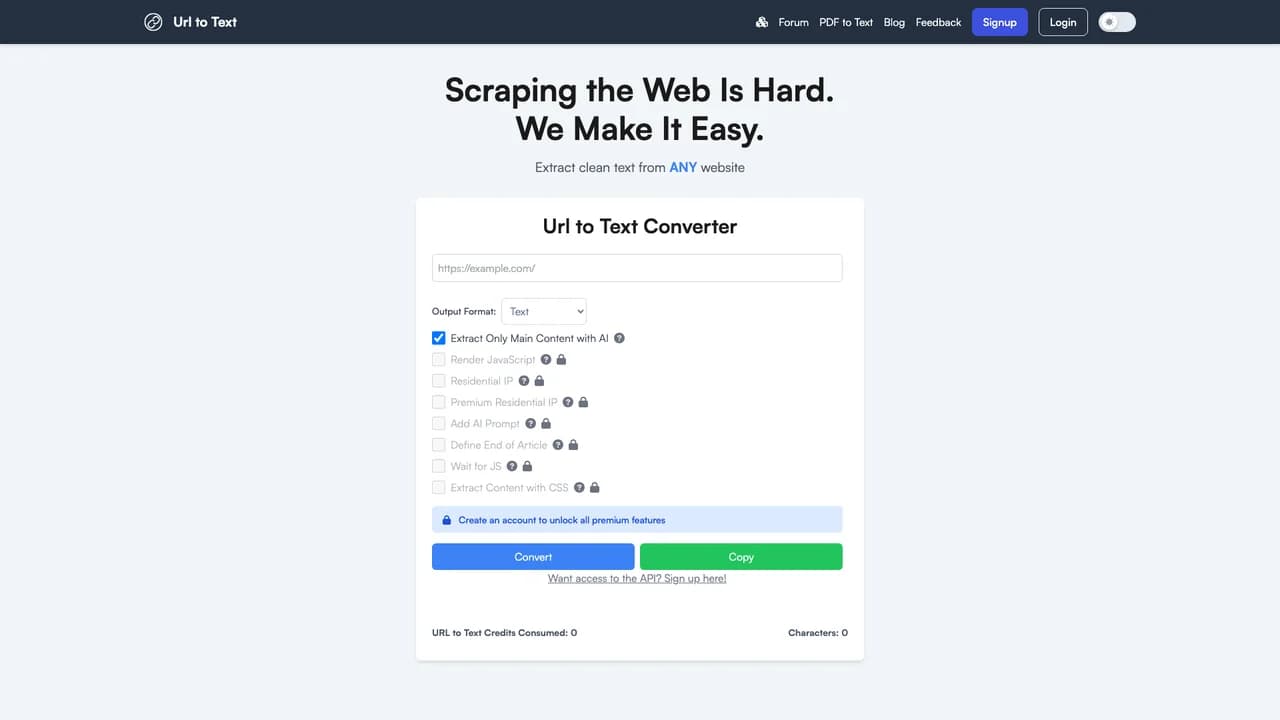
URLtoText is a simple and user-friendly online platform that converts any valid webpage URL into clean text or Markdown format. It supports complex website structures, including JavaScript-heavy pages, and offers AI prompt integration along with residential IP options to bypass anti-bot measures. Originally developed as a testing interface for an efficient web scraping tool designed for AI training, it has evolved into a free and reliable text extraction solution that delivers clean text quickly—no programming required. Future updates will introduce paid plans and an API interface to meet higher demands and ensure scalability.
Key Features of urltotext?
Alternatives to urltotext

uprock
UpRock is an innovative decentralized platform that transforms users' idle internet bandwidth into valuable data resources for AI applications. Through a mobile-first decentralized physical infrastructure network (DePIN), UpRock enables real-time, fair, and geographically diverse web data collection and analysis. Users are rewarded with UpRock Tokens ($UPT) for contributing their bandwidth, fostering a community-driven ecosystem that democratizes AI data and breaks down data monopolies. The platform features an AI-powered insights exchange dashboard, delivering personalized, uncensored insights and APIs tailored for business intelligence, open-source intelligence, and data API markets.

reworkd-ai
Reworkd AI is a comprehensive automation platform that leverages AI agents to understand web pages, generate extraction code, run crawlers, validate results, and deliver structured data, enabling businesses to efficiently build web data pipelines. The platform eliminates the need for manual coding, infrastructure setup, and maintenance, allowing organizations to scale data extraction capabilities reliably and cost-effectively. Features such as self-healing crawlers and in-depth analytics ensure data accuracy and operational efficiency, supporting a wide range of data types and business processes.

webscrapingai
WebScraping.AI simplifies the web scraping process by handling complex technical challenges such as proxy rotation, browser rendering, CAPTCHA solving, and HTML parsing. Users provide a URL, and the API returns fully rendered HTML, plain text, or structured data extracted from the webpage. It supports JavaScript-heavy websites by rendering pages using real Chrome browsers, ensuring accurate data capture. The platform also enables access to geo-restricted content through residential proxies and delivers targeted insights via AI-assisted data extraction, allowing developers to focus on data utilization rather than scraping infrastructure.

tensorlake
Tensorlake is a comprehensive AI data cloud platform designed to transform unstructured documents, images, and other file types into structured, ingestible data suitable for large language models and AI applications. It offers robust document ingestion APIs capable of parsing complex document layouts, preserving semantic structures such as tables, graphics, and text order. Additionally, Tensorlake provides a Python-based serverless workflow engine that enables users to build scalable, event-driven data pipelines and automate data transformations without managing infrastructure. The platform supports high-volume document processing with low latency and seamlessly integrates with databases and AI models to maintain data freshness and accessibility for efficient retrieval and analysis.

thunderbit
Thunderbit is an AI-powered web scraping tool that simplifies and automates data extraction from websites, PDFs, and images—no coding required. Delivered as a Chrome extension, it helps sales, marketing, real estate, and e-commerce teams quickly capture structured data such as leads, contacts, and product details. Leveraging advanced AI technology, Thunderbit automatically detects, formats, and organizes data in real time, with seamless export options to popular tools like Google Sheets, Airtable, Notion, and Excel. Its intuitive interface and natural language input make complex scraping tasks simple and efficient, eliminating the need for manual copy-pasting and significantly boosting productivity.

firecrawl
Firecrawl is an advanced web scraping and data extraction API designed for developers, capable of converting website content into clean markdown, structured data, and other formats ideal for AI applications. It supports dynamic JavaScript rendering, bypasses anti-bot mechanisms, and handles authentication, offering a scalable solution for large-scale web data collection. Firecrawl can crawl entire websites, extract specific data points, and efficiently follow links, making it perfectly suited for building retrieval-augmented generation systems, content monitoring, and research purposes.


