
ttslabs
Twitch streaming voice alert tool that generates customizable text-to-speech alerts with integrated donation controls
Monthly Visits
15.6K
Avg. Session Duration
1 min
Category Rank
#11404
Bounce Rate
0.5%
What is ttslabs?
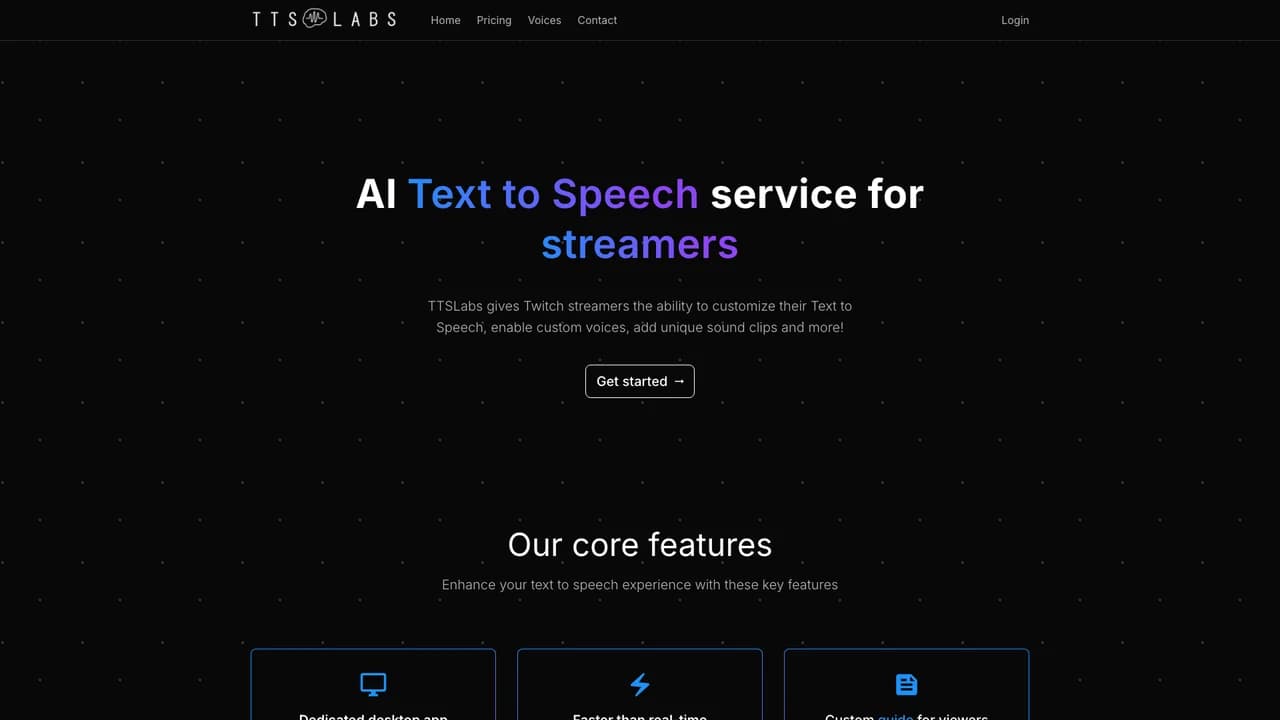
TTSLabs enhances the Twitch streaming experience by offering a dedicated desktop application that allows streamers to customize text-to-speech alerts using a variety of voice options and unique soundboard clips. It supports rapid audio generation, producing 20 seconds of speech in under 3 seconds, and integrates seamlessly with Streamlabs and StreamElements for effortless donation management. An advanced profanity filter helps maintain a safe streaming environment, while the viewer guide improves interaction by displaying available voices, sound clips, and minimum donation amounts. This tool enables streamers to create engaging and personalized audio experiences for their audience.
Key Features of ttslabs?
Alternatives to ttslabs

lang-lang-dubbing
Langlang AI Voice is a comprehensive text-to-speech platform that converts written text into natural-sounding speech across more than 30 languages, including Chinese, English, German, French, Italian, Spanish, and Indonesian. The platform offers over 200 voice models with a wide range of emotional styles, from happy and sad to excited and fearful. It supports advanced features such as SSML tags for precise speech control, multi-speaker narration, background music integration, and sound effects. Users can generate high-quality audio suitable for commercial use and retain full copyright ownership, making it ideal for video voiceovers, audiobook production, advertising, and educational content.

yueyin-voice-synthesis
Yueyin Peiyin is a comprehensive voice generation platform developed by Zhipianbang that converts text into natural and fluent speech. The platform features an extensive voice library with a wide range of voices across different genders and age groups, supporting Mandarin, various regional dialects, and multiple international languages to meet diverse creative needs—from video narration to educational content. Combining automated speech synthesis with professional human voice-over services, Yueyin Peiyin offers flexible solutions tailored to different quality requirements and budget constraints.

ciniao-voice
Ciniao Voice is an all-in-one text-to-speech platform that leverages advanced speech synthesis technology to convert written content into natural and fluent audio. The platform offers over 200 diverse voice options, including popular voices such as Magic Yunxi and Magic Xidu, and supports multiple languages and dialects including Mandarin, English, Cantonese, Sichuanese, Northeastern Chinese, Hunanese, and Taiwanese. Users can customize speech rate, pitch, volume, and background music to easily create professional-grade audio content, widely applicable in scenarios such as short videos, film and television dubbing, educational materials, and audiobooks.

ttsvox
TTSVox is a web-based text-to-speech platform that converts any text into natural, high-quality audio. Supporting over 50 languages and 200 voice options—including various accents and genders—users can customize speech output according to their needs. Designed with accessibility and broad applicability in mind, TTSVox is ideal for applications such as video narration, online education, IVR systems, and audio articles. The service is available for unlimited use without the need for downloads or installations, making it convenient for students, professionals, and content creators to use anytime.

sesame-ai
Sesame AI is an advanced conversational speech model capable of generating highly natural and human-like speech synthesis. Unlike traditional text-to-speech systems, the Sesame model integrates both text and audio context to produce fluent, expressive speech that accurately captures emotion, intonation, and conversational dynamics. Built on a large-scale Transformer architecture, it supports multilingual and multi-voice output with real-time generation and high customizability. Sesame AI is ideal for developers, content creators, and enterprises aiming to build authentic, natural voice interaction experiences.

typecast-ai
Typecast AI is an advanced AI voice generation platform that converts text into realistic speech with precise control over tone, pitch, speed, and emotion. Powered by its proprietary Speech Synthesis Foundation Model (SSFM), Typecast delivers natural and expressive speech in over 20 languages. The platform offers access to more than 550 AI voice actors and virtual avatars, enabling users to efficiently produce audio and video content without the need for traditional voice recording studios. With an intuitive interface and seamless integration capabilities, Typecast streamlines workflows for content creators, educators, marketers, and developers.


