
elevenlabs
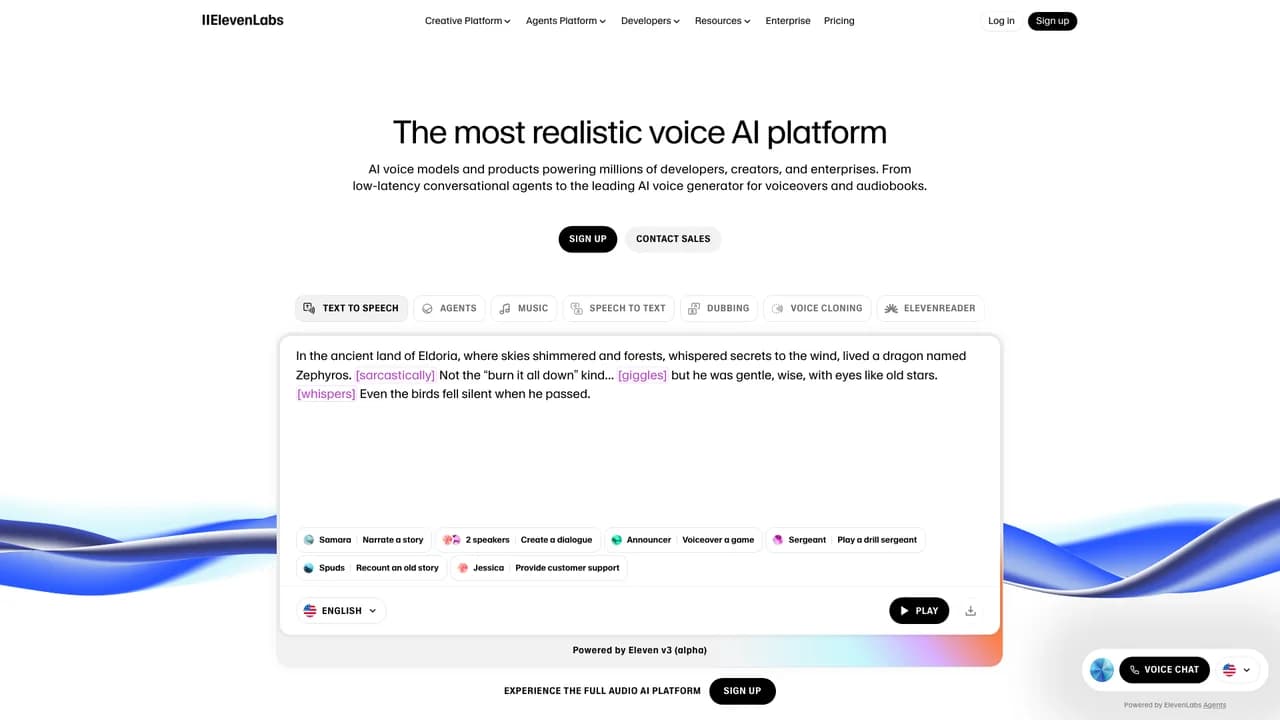
Text-to-speech platform that generates natural multilingual voices and supports voice conversion
Monthly Visits
22.5M
Avg. Session Duration
5 min
Category Rank
#38
Bounce Rate
0.4%
What is elevenlabs?
ElevenLabs is a leading AI audio technology company focused on creating highly realistic, emotionally expressive synthetic voices. The platform supports text-to-speech, speech recognition, voice conversion, and multilingual dubbing across more than 30 languages. Leveraging deep learning models, ElevenLabs delivers natural intonation, rhythm, and emotional nuance, making it ideal for applications such as audiobook narration and conversational AI voice agents. Committed to responsible AI use, the company provides scalable solutions for individuals, creators, and enterprises.
Key Features of elevenlabs?
Pricing
Free Tier: Experience ElevenLabs with a limited free trial.
Subscription Plans: Subscription plans start at a competitive price point, offering access to additional features and voices.
Disclaimer: Please note that pricing information may not be up to date. For the most accurate and current pricing details, refer to the official ElevenLabs website.
Alternatives to elevenlabs

f5-tts
F5-TTS is a cutting-edge AI text-to-speech synthesis platform that converts text into highly natural and expressive speech in real time. The system employs a fully non-autoregressive architecture based on Flow Matching, combined with Diffusion Transformer (DiT) and ConvNeXt V2, to achieve superior alignment between text and speech. It supports zero-shot voice cloning from minimal audio samples, multilingual synthesis—especially in Chinese and English—and fine-grained control over emotion and speaking rate. Trained on large-scale, multilingual datasets, F5-TTS achieves industry-leading levels of naturalness and robustness, making it suitable for diverse applications such as audiobooks, virtual assistants, content creation, and accessibility tools. As an open-source project, it encourages collaboration and integration by developers.

wavel-ai
Wavel AI is a comprehensive AI-powered platform for audio and video content creation, supporting text-to-natural-speech conversion, voice cloning, audio-video transcription, and multilingual video dubbing. It enables speech generation in over 40 languages and transcription and translation in more than 100 languages, delivering high accuracy and extensive customization options such as pitch, emotion, and accent adjustment. Designed for content creators, enterprises, educators, and developers, Wavel AI enhances accessibility, localization, and global distribution of multimedia content.

voicemaker
Voicemaker is an advanced online TTS tool that converts text into high-quality, lifelike speech. Supporting multiple languages and accents, it is suitable for a wide range of applications such as videos, audiobooks, online education, and customer service. The platform offers customizable features including speech rate, pitch, volume, pauses, and audio effects, enabling users to create personalized audio content. With a user-friendly interface and API support, it is ideal for content creators, businesses, and developers. The generated audio comes with usage rights.

listnr-ai
Listnr AI is a leading text-to-speech software that efficiently generates human-like voiceovers and audio content. The platform supports over 1,000 voices across 142 languages, enabling users to easily create natural-sounding audio for podcasts, online education, video narration, audiobooks, and more. It offers extensive customization options, including voice style, emotion, pitch, and speaking rate, along with an API for seamless integration into various applications and services. Listnr AI simplifies audio content creation, making it accessible and user-friendly for content creators, educators, businesses, and developers.

texttovoiceonline
Texttovoice.online enables users to quickly and easily convert written text into realistic and engaging speech audio. It supports a wide range of languages and voice options, including advanced voice cloning and emotional voice styles to enhance expressiveness. The platform is designed for content creators, educators, and professionals who need high-quality voiceovers for videos, podcasts, audiobooks, and interactive applications. Users can customize voice characteristics and export audio in common formats such as MP3 and WAV, streamlining the voice content production process without the need for recording equipment.

speechki
Speechki is a comprehensive text-to-speech solution that enables users to convert written content into highly realistic audio using an extensive library of voices and languages. The platform features an intuitive visual editor for adjusting tone, speed, and pitch, along with advanced tools for prosody and phoneme control. With support for chapter-based formatting, real-time proof listening, and voice cloning, Speechki is suitable for a wide range of applications, including online learning, podcast production, and global content distribution. Its seamless integration capabilities allow users to easily share and distribute audio across various platforms.


